
Eight products live. Two on the way. One decision framework.
The Meridian Suite is Senticit's unified platform for AI & IT governance. Radar diagnoses, Atlas authors your policy and Compass attests it, Slant monitors your clinical models, Sentinel oversees the rest of your AI stack, Ledger™ collects the evidence continuously, Pulse reports risk to the board, and Signal measures momentum against reality — with Tether and Marshal arriving to extend the same discipline to autonomous agents. All of it runs on one shared Evidence Room, one identity layer, and one decision framework.
Why a suite — and not ten point tools
Every Meridian product is useful on its own. Together, they collapse the seams where AI risk and compliance evidence usually get lost.
One view of risk
Ten products, one scoring model and one Evidence Room, so executives get a single reading across compliance, AI governance, policy, momentum, and the agents acting on the organisation's behalf.
Closed-loop oversight
Findings from Radar feed the Evidence Room; live signals from Slant and Sentinel trigger alerts; Signal reconciles ambition against actual posture.
Accreditation-aligned by default
Every product maps to SOC 2, HIPAA, NIST 800-53, NIST AI RMF, ISO 27001, ISO 42001, and the EU AI Act — no manual control mapping.
Built on Meridian Suite judgment
The Meridian Suite encodes the same compliance-led decision framework Senticit uses inside its Meridian Suite engagements.
Shared services every product runs on
Built once, consumed everywhere — the reason Meridian scales as a suite instead of ten disconnected apps.
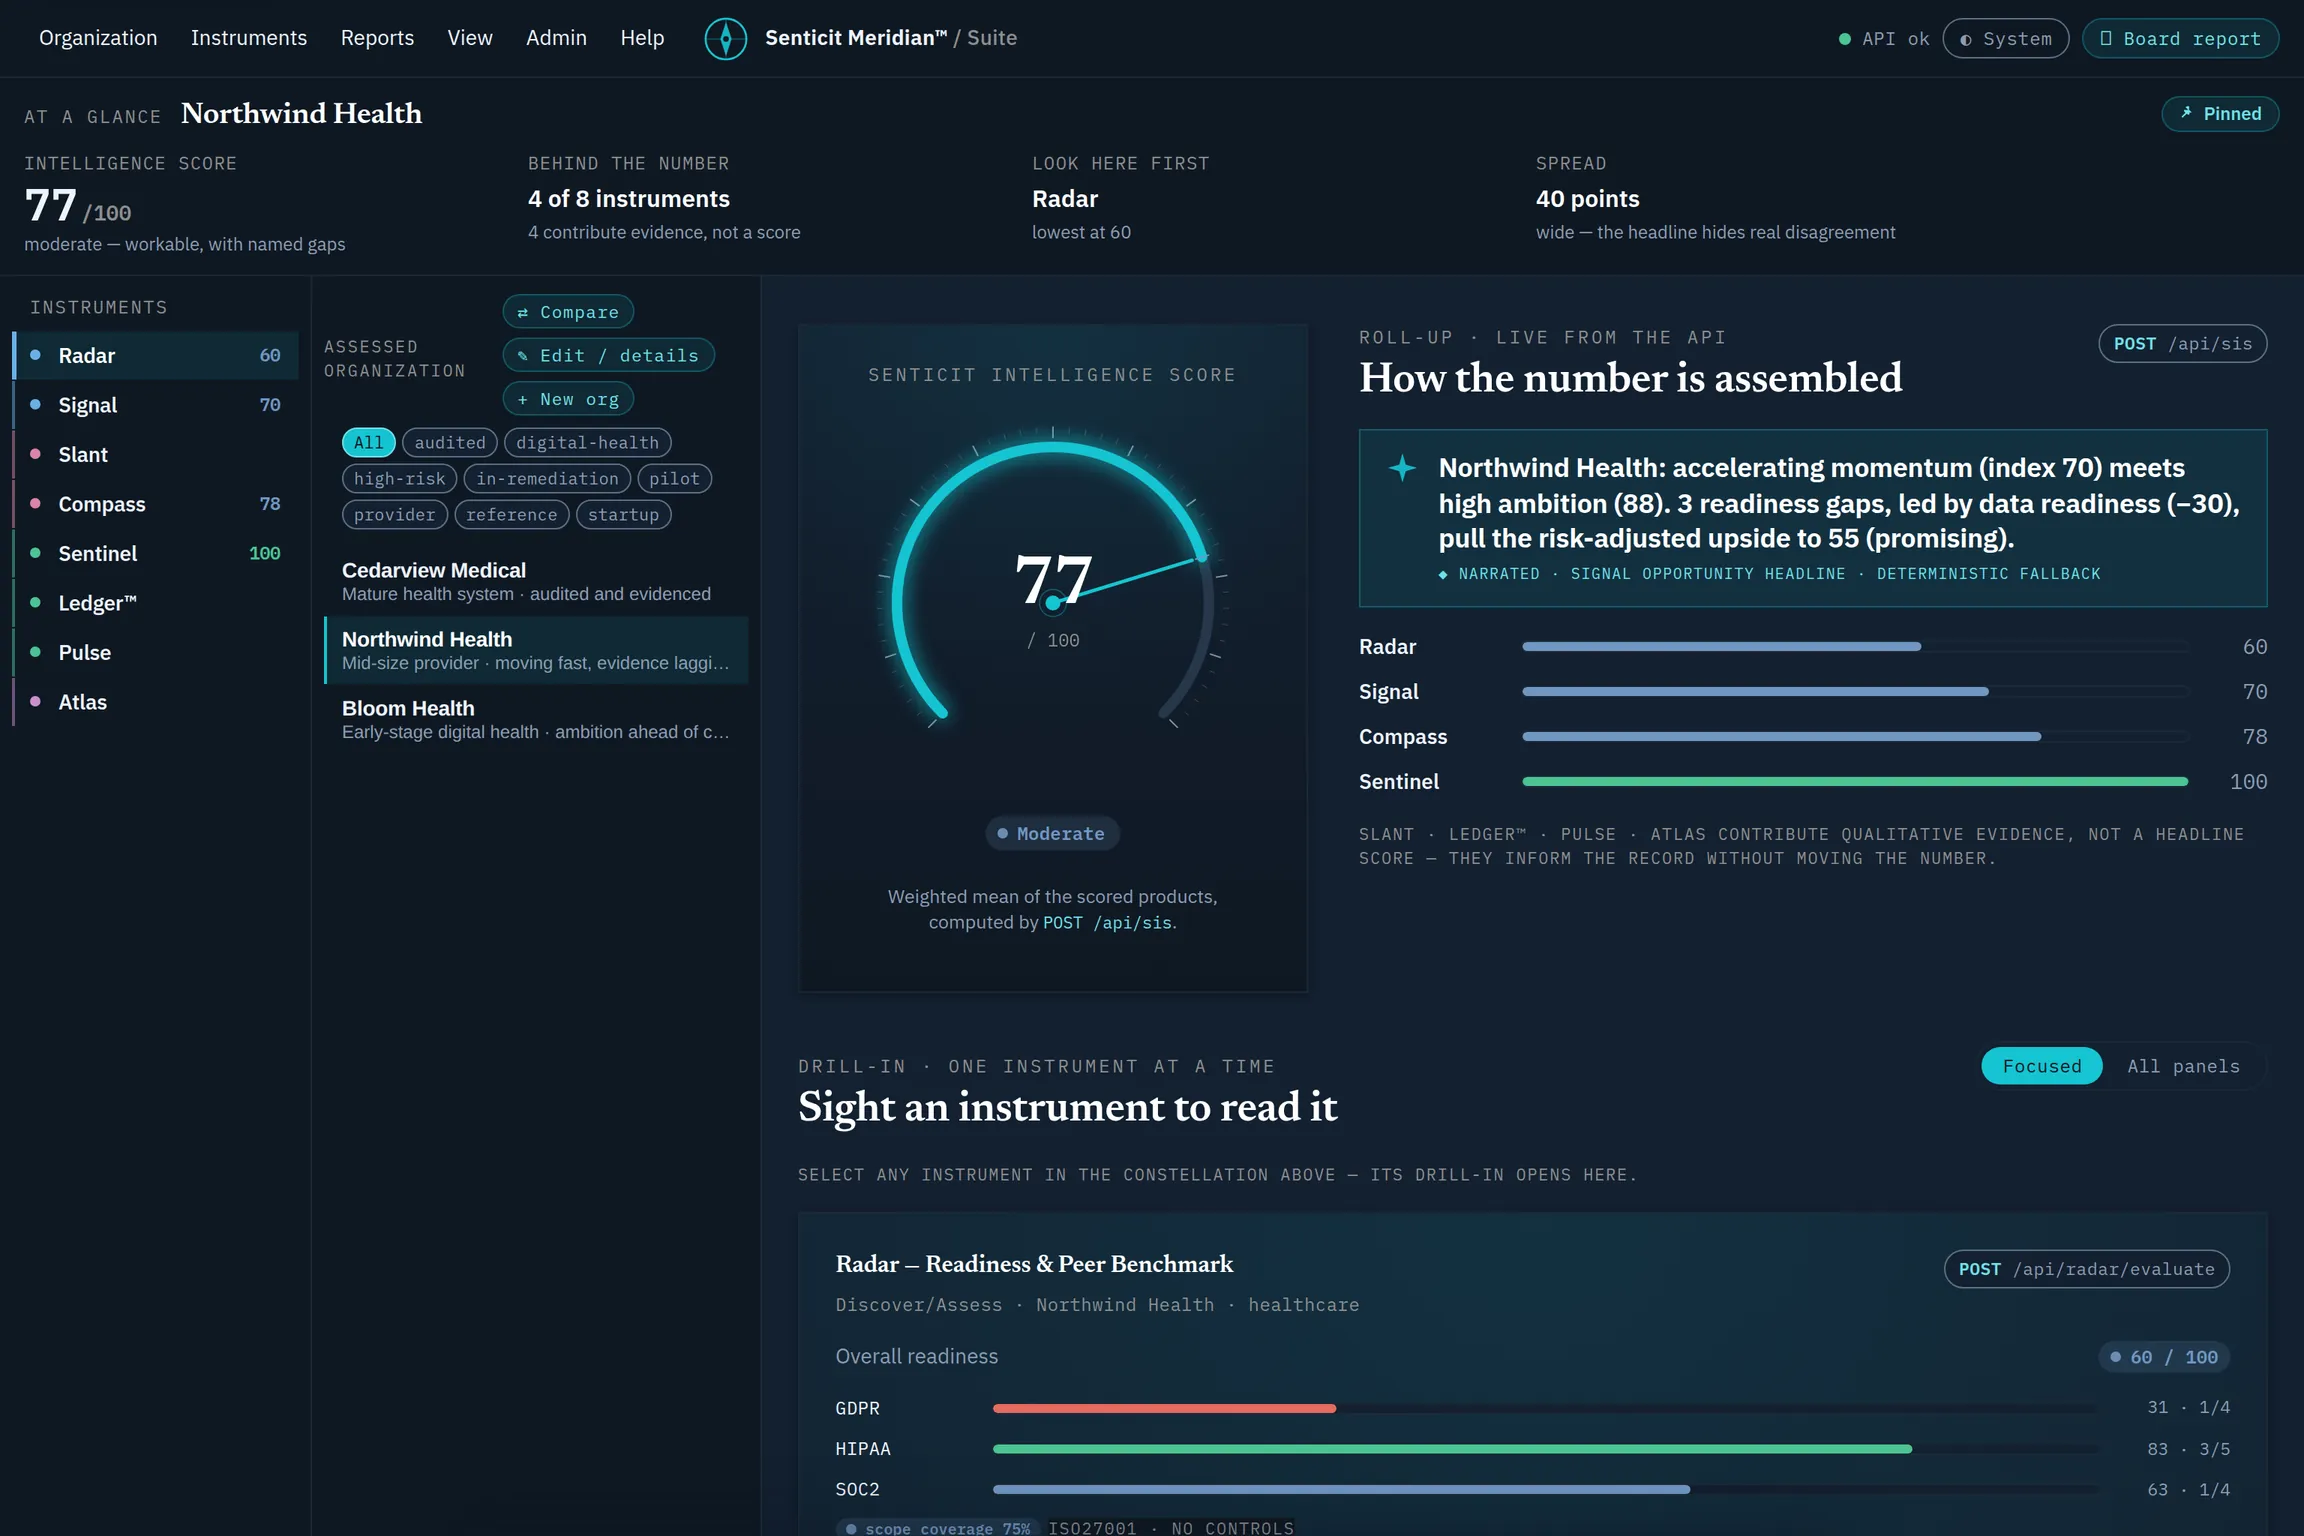
Senticit Intelligence Score (SIS)
A composite board-facing score. Today it is a weighted mean of the four instruments that emit a normalized score; the other products contribute evidence and findings rather than a number.
Consumed by: Radar · Signal · Compass · Sentinel
Evidence Room
Unified, versioned store of policies, tickets, logs, attestations, and assessment exports — one document store the whole suite writes to.
Consumed by: All eight built products
Identity & Tenancy
Multi-tenant auth, org hierarchy, and tier gating (Public / Prospect / Sentinel / Vanguard / Command) shared across every product.
Consumed by: All eight built products
Notification & Report Engine
Scheduled PDF/email reports, drift alerts, renewal reminders — one delivery layer instead of ten bespoke ones.
Consumed by: All eight built products
Cross-Product Recommendation Engine
Nudges like: 'Your Radar gap in vendor risk correlates with a Sentinel drift event.' Meaningful once real usage data exists across products.
Consumed by: All eight built products
Ten products, one operating model
Each Meridian product owns a specific stage of AI and IT oversight — and shares scoring, policy, and evidence with every other product in the suite.
Meridian Radar™
Free 8-domain compliance readiness assessment — the top of the funnel.
Every prospect's fixed reference point. Radar scores your organization across 8 domains in ~12 minutes and produces a prioritized remediation plan that hands off into the rest of the suite.
Feature set
Core Assessment
- 8-domain scoring (security, infrastructure, ops, vendor risk, data governance, IR, policy, training)
- Weighted 0–100 composite readiness score
- Auto-generated prioritized remediation plan
- Industry + company-size peer benchmarking
Lead Capture & Growth
- Email-gated PDF results
- Progressive profiling
- Twenty CRM webhook on completion
- 30/60/90-day retake reminders
Reporting
- Branded prospect-facing PDF
- Sales-facing summary with hot-lead flags (sub-40 = urgent)
Meridian Slant™
Continuous clinical AI governance — bias, drift, and accreditation-readiness.
The flagship paid product for healthcare. Slant monitors clinical AI models for bias across patient subgroups, tracks drift over time, and produces ACR / IAC / TJC accreditation-ready reports.
Feature set
Bias & Fairness
- Subgroup breakdown (age, sex, race/ethnicity, insurance, site)
- Statistical parity / equalized odds / calibration
- Threshold-based disparity alerting
Drift Detection
- Input distribution drift
- Output/prediction drift
- Performance decay trendlines
- Client-configurable re-evaluation cadence
Accreditation
- ACR AI reporting template
- IAC reporting template
- TJC survey-ready export
- CISO-cosigned quarterly attestation
Deployment
- HIPAA-grade BAA-covered hosting
- Model registry
- API/webhook inference log ingestion
Meridian Sentinel™
Continuous oversight infrastructure for any AI stack — model-agnostic.
Catches unsafe reasoning, drift, and bias before they reach customers, across whatever LLM or ML tools a client runs. Trace Logic, an 8-domain Ethics Gate, and anomaly detection — not healthcare-specific.
Feature set
Trace Logic
- Per-inference reasoning trace capture
- Immutable, timestamped audit log
- Searchable trace history
- Exportable bundles for incident or regulator request
Ethics Gate
- 8-domain checks (bias, harm, factuality, scope, PII, manipulation, safety, escalation)
- Pre-inference blocking mode
- Post-inference flagging mode
- Per-client severity thresholds
Drift & Anomaly
- Behavioral drift from baseline
- Anomaly spikes in flagged content
- Bias monitoring generalized from Governance methodology
Integration
- OpenAI, Anthropic, open-source, custom pipelines
- API-first architecture
- Lightweight SDK/middleware
Meridian Signal™
Forward-looking AI momentum score with a Tension Resolver.
A free 3-minute AI momentum score that reconciles ambition against actual governance readiness. When Signal's optimism outruns Radar and Sentinel posture, it flags the gap in plain language.
Feature set
Intake & Scoring
- 7-question thin-slice intake (under 3 minutes)
- Optimism Index with named readiness band (Cautious → Leading)
- Ungated first pass — low-friction top-of-funnel
Trajectory & Prediction
- Historical trajectory chart
- 90-day activation probability estimate
- Peer segment comparison
Tension Resolver
- Cross-pull from Radar + Sentinel
- Ambition-vs-readiness gap flag
- Plain-language narrative output
Reporting
- Shareable PDF summary
- CRM webhook on completion
- Internal lead-scoring signal
Meridian Compass™
AI ethics — define, score and attest the guardrails the rest of the suite runs on.
The suite's ethics layer. Compass maps your obligations to the frameworks that impose them, scores each proposed AI use against the guardrails, derives the timeline those obligations fall due on, and produces the attestation an auditor will accept. It is one of the four instruments that emit a score into the Senticit Intelligence Score.
Feature set
Framework mapping
- Obligations mapped to the frameworks that impose them
- Coverage gaps named rather than averaged away
- SOC 2, HIPAA, NIST AI RMF, ISO 42001 and the EU AI Act
Obligation timeline
- What falls due, when, and on whom
- Derived from the mapping rather than kept in a spreadsheet
- Disclosure readiness assessed per obligation
Audit package
- A single assembled bundle an auditor will accept
- Evidence pulled from the shared Evidence Room
- Regenerated rather than rebuilt each cycle
Meridian Ledger™
Continuous compliance monitoring — always-on evidence collection and control health.
Formerly Vigil. Ledger turns audit preparation into a background process: it collects evidence continuously, monitors whether each control is actually working, and assesses continuity so a control that quietly stopped running is visible now rather than at the next audit.
Feature set
Evidence collection
- Always-on rather than a pre-audit sprint
- Written to the shared Evidence Room
- Findings carry named owners
Control monitoring
- Per-control health, continuously tested
- Failures surfaced when they happen
- Mapped to SOC 2, HIPAA, ISO 27001 and NIST 800-53
Continuity
- A control that stopped running is a finding, not a silence
- Gaps in the record reported as gaps
- Audit-ready packages on demand
Meridian Pulse™
Executive risk telemetry — a live, board-ready view of technology and security risk.
Pulse scores risk across internal environments, third parties and AI systems, aggregates it to the portfolio level, and produces the board summary — replacing a static quarterly deck with evidence of which safeguards are working today. It also reports the basis of its own posture, so a reader can see what the number rests on.
Feature set
Risk scoring
- Scored across internal, third-party and AI systems
- Aggregated to portfolio level
- Posture basis reported alongside the score
Board reporting
- Board-ready summary generated from live data
- Replaces the static quarterly deck
- Escalation paths for what is degrading
Honesty rules
- Thin coverage is reported as thin coverage
- The basis of the posture is stated, not implied
- Contributes evidence and findings rather than a headline score
Meridian Atlas™
AI policy workspace — author, version and operationalize the policies you are judged on.
Atlas is where AI policies are written, revised with an integer version history, and turned into operational controls with a named owner. It grades how enforceable a policy actually reads, and reports what the latest revision DID — including the case where a policy's score rose while it quietly stopped saying "must".
Feature set
Authoring & versioning
- Integer-versioned drafts and revisions
- Published, draft and retired states tracked
- Operational controls and a named owner per policy
Drafting quality
- Graded on how enforceable the policy text reads
- Scope, mandatory language, accountability, cadence, enforcement
- Deterministic and offline
Amendment read
- What the latest revision actually did, per dimension
- Flags a revision that weakened the guardrail
- Names the case where the score rose as the policy stopped binding
Meridian Tether™
Autonomous-agent monitoring — discover every agent, baseline it, catch drift.
The agent layer's eyes. Most organisations cannot say how many autonomous agents they run or what those agents can touch. Tether discovers every agent it can reach — including shadow agents — baselines how each one behaves, and flags drift against that agent's own history. It observes and proves; it never sits in the execution path.
Feature set
Discovery & Registry
- Auto-surfaces agents, including shadow agents in Zapier, copilots and one-off scripts
- Owner, purpose and models recorded per agent
- The tools and data inside each agent's scope
Behaviour & Drift
- A behavioural baseline per agent
- Scope creep and unusual tool use flagged against that agent's own history
- Failure-spike and anomaly detection
Observability
- Action and tool-call detail across a multi-step run
- Per-agent risk scoring into the Intelligence Score
- Alerting to the agent's named owner, with evidence attached
The boundary
- Monitoring and evidence, not inline enforcement
- Hands off to an enforcement layer where one exists
- Never sits in the execution path
Meridian Marshal™
Agent-workflow governance — trace the workflow, approve the risky steps, prove the chain.
The agent layer's record. When agents chain steps and hand off to one another, there is no account of why the workflow acted. Marshal traces every step, raises a named human approval where risk demands it, and hands auditors the whole chain. Its gates are approval checkpoints: it governs alongside the pipeline and never halts it.
Feature set
Lineage & audit
- A queryable, replayable chain: prompt → tool → data → decision → output → actor
- An immutable, timestamped record of every step, approval and override
- Auditor- and customer-shareable trust reports generated from the trail
Approvals
- Named human approvers on high-risk steps
- Escalation, delegation and SLAs built in
- Who approved, who declined, and what the workflow did next
Policy conformance
- Workflow steps evaluated against Compass and Atlas policies
- Conformant, exception, or awaiting approval recorded per step
- Continuous evidence for SOC 2, HIPAA, EU AI Act and NIST AI RMF
The boundary
- Approval-only — Marshal never blocks a running workflow
- Governs alongside the pipeline, never inside it
- If Marshal is unavailable, customer workflows keep running
How the suite works together
Meridian is sequenced the way real AI and IT programs mature — diagnose first, govern next, oversee continuously, measure momentum against reality, then extend the same discipline to the agents now acting on your behalf.
- 1
Diagnose with Radar
A free 8-domain assessment establishes your composite readiness score and surfaces the highest-leverage gaps.
- 2
Author the policy with Atlas
The guardrails you will be judged on, written, versioned, and turned into controls with a named owner.
- 3
Attest it with Compass
Obligations mapped to the frameworks that impose them, scored, timelined, and assembled into a package an auditor will accept.
- 4
Govern clinical AI with Slant
Bias, drift, and accreditation readiness scored continuously across every clinical model in production.
- 5
Oversee the rest of your AI stack with Sentinel
Trace Logic and the 8-domain Ethics Gate catch unsafe reasoning, drift, and bias across any LLM or ML tool.
- 6
Collect the evidence with Ledger™
Always-on evidence collection and control monitoring, so a control that quietly stopped working is visible now rather than at the next audit.
- 7
Report to the board with Pulse
Live risk telemetry across internal, third-party and AI systems, with the basis of the posture stated alongside the number.
- 8
Prioritize with Signal
The AI momentum score and Tension Resolver tell leadership where ambition is outrunning actual governance readiness.
- 9
Discover your agents with Tether
Every autonomous agent you run — including the ones nobody registered — inventoried, baselined, and watched for drift against its own history.
- 10
Prove the workflow with Marshal
The chain of prompt, tool, data, decision and actor captured end to end, with named human approval on the steps that carry real risk.
See where your AI & IT program scores today
Start with the free Radar assessment. Your composite score becomes the entry point to the rest of the Meridian Suite — and the first input into your Senticit Intelligence Score.